CognifyMedia’s OCR engine is built for enterprises handling high volumes of complex, multilingual content. From scanned files and handwritten notes to mixed-format documents, it delivers accurate, layout-preserving text extraction, keeping tables, columns, and structures intact.
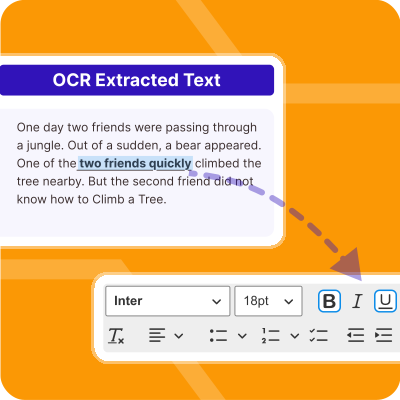
With built-in editing, teams can refine content instantly without switching tools. It supports bulk processing, handles hundreds of files at once, and works seamlessly across 14 languages, making it perfect for global, large-scale operations.

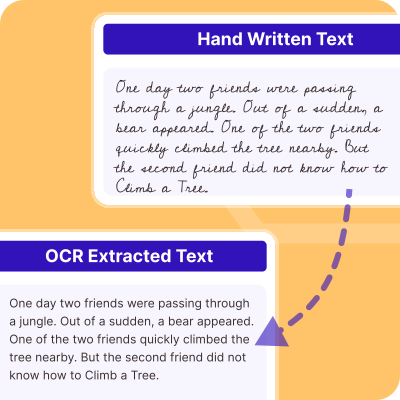
Notes, forms, and written records can’t be searched, copied, or processed, leaving valuable information locked in analog formats.

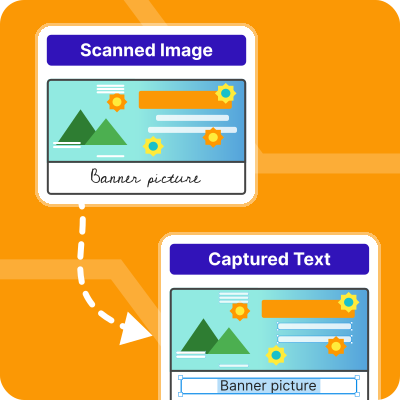
Scanned documents are treated as images, making it impossible to extract or update content without manual rework.

Teams struggle to handle diverse languages without native OCR support, slowing down processes that depend on translation or content reuse.

Standard tools strip away formatting, tables, columns, and structure, forcing teams to rebuild documents before they’re usable.
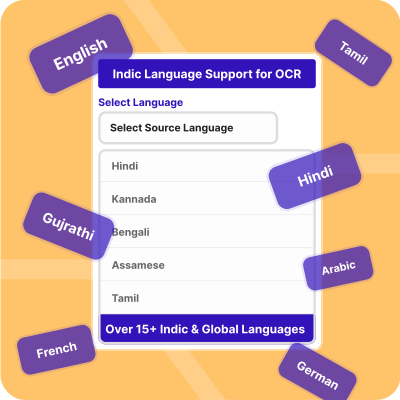
CognifyMedia supports English and Indic languages like Assamese, Hindi, Telugu, Bengali, Kannada, Marathi, Odiya, Gujarati, Punjabi, Malayalam, Tamil, Manipuri, Sindhi, and Urdu, along with global languages including Arabic, Dutch, French, German, Italian, Polish, Romanian, Russian, Spanish, Turkish, and Ukrainian.
math-heavy docs