Intelligent Information Extraction From Insurance Documents
This solution automates the extraction of critical information from complex insurance documents,
reducing manual effort and Errors & Omissions (E&O) risk. It handles diverse document layouts and unstructured data while
delivering accurate, consistent results at scale for high-volume processing.
Contents
- Objective
- Business Impact
- Challenge
- Solution
- Technical Architecture
- Result
Objective
The objective of this initiative was to reduce the manual effort involved in extracting critical
information from insurance documents, thereby lowering Errors & Omissions (E&O) risk for insurance brokers.
A key requirement was to ensure that the solution delivered consistently high-quality outputs, avoided performance
degradation over time, and supported high throughput, enabling the processing of large volumes of documents daily without bottlenecks.
Business Impact
No two carriers lay out a policy the same way, so the figures a broker advises on, get found and copied by hand. A limit read wrong becomes advice given on a number that is not in the policy, and that is where Errors and Omissions claims start.
- 95% accuracy or better on the 10 critical data points. Fewer figures reach a client without being checked against what the policy actually says.
- Capacity without hiring. Manual review and correction fall away, so document volume can rise on the existing team.
- Quality does not drift. Every document is validated against a defined structure, so the hundredth one is read as carefully as the first.
- Nothing gets replaced. It runs inside the document processing engine the broker already operates.
Challenge
Insurance documents are inherently complex due to highly variable layouts and formatting across insurers
and document types. Critical data points—such as coverage details, limits, endorsements, schedules,
and remarks—often appear across multiple pages and may be embedded within tables, free-form text, or scanned content.
- Accurately identifying and extracting critical data points from unstructured and semi-structured documents
- Handling significant layout variability across carriers and lines of business
- Ensuring consistent extraction quality over time with no model or rule-based drift
- Maintaining high throughput to support production-scale document processing
Solution
An end-to-end intelligent document processing solution was developed to automate the extraction of critical
information from insurance documents. The solution creates a seamless processing flow from document ingestion
to structured data output, reducing manual effort and minimizing Errors & Omissions (E&O) risk. It is designed
to handle complex, multi-page documents with varying layouts while ensuring consistent accuracy and scalability
for high-volume processing.
Intelligent Information Extraction
The system processes insurance documents by first identifying relevant content and normalizing it into a consistent format. Advanced
extraction logic combined with schema-driven intelligence ensures that required data points are captured accurately, regardless of document
structure or layout variations. Strict validation mechanisms are applied to maintain data quality and prevent inconsistencies, enabling reliable
and repeatable results in production environments
Scalable & High-Performance Processing
The solution is built to support large-scale document volumes without impacting performance or accuracy. It is optimized to process documents quickly and reliably, making it suitable for enterprise production environments where speed and consistency are critical.
The processing pipeline efficiently handles multiple documents in parallel and ensures that extraction quality remains stable over time. By limiting advanced processing to only relevant content, the system achieves high throughput while keeping operational costs under control.
Quality Control & Data Validation
Maintaining accuracy and consistency is a core focus of the solution. Multiple validation layers are applied to ensure extracted data meets predefined structure and quality standards before it is finalized.
Schema-based validation and rule checks help eliminate incomplete, incorrect, or inconsistent outputs. This approach significantly reduces the need for manual review and ensures long-term reliability without degradation in extraction quality.
System Integration
The solution is designed for easy integration with existing enterprise systems and workflows. It operates as a modular service that can be embedded into current document management or processing platforms.
This flexible architecture allows organizations to adopt the solution without major system changes, enabling faster deployment and smoother adoption while enhancing overall document processing efficiency.
Technical Architecture
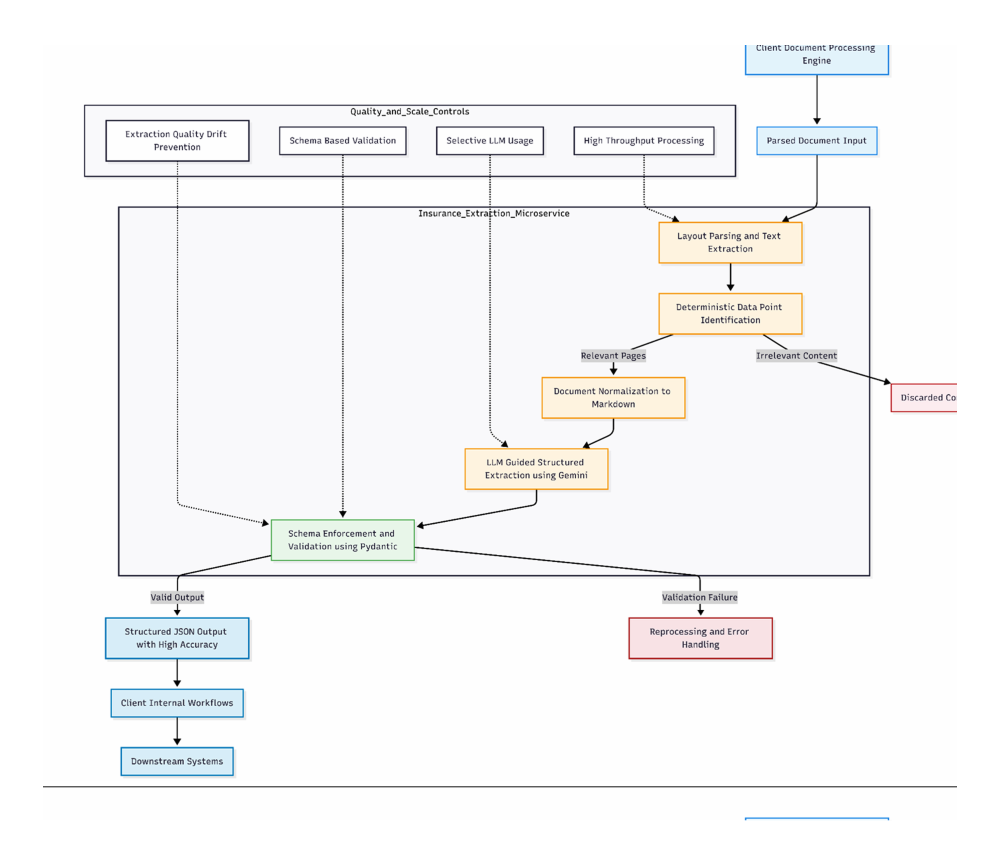
Enterprise-Ready Document Processing and Validation Pipeline
- Documents are ingested through the client’s document processing engine and routed to a dedicated extraction microservice.
- Layout parsing and deterministic data point identification are applied to isolate relevant content and eliminate noise early.
- Relevant pages are normalized into a layout-agnostic format to ensure consistent interpretation across document types.
- Schema-guided large language model extraction converts normalized content into structured data.
- Strict schema enforcement and validation checks ensure data accuracy, consistency, and long-term reliability.
- Validated structured outputs are delivered to downstream enterprise systems, with reprocessing and error handling for exceptions.
Result
- Achieved ≥95% extraction accuracy for 10 critical data points that can appear anywhere within insurance documents, including complex and multi-page layouts.
- Significantly reduced manual review and correction efforts, directly lowering E&O risk for insurance brokers
- Successfully deployed as a production microservice within the client’s internal document processing engine, enabling seamless integration with existing systems and workflows
- Supported large-scale document processing with high reliability, fast turnaround times, and no compromise on accuracy.
Contact Us
Your response has been saved. Thank you.
We will reach out to you shortly.
Read More
See the latest of our technologies in our blog section.
The Hidden Costs of LLM APIs That Per-Token Pricing Doesn’t Tell You
This article is part of a series on buildi ...
How We Unified Three LLM Providers Behind One Interface
This article is part of a series on buildi ...
Your LLM Prompt Won’t Save You From This
This article is part of a series on buildi ...
© 2026 krtrimaIQ Cognitive Solutions. All Rights Reserved
Email: info@krtrimaiq.ai